DeepToSeek
CerebrasFreemium
Overview
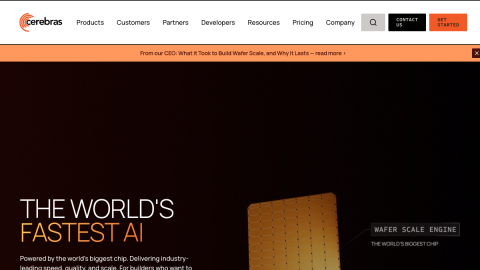
Cerebras runs inference on wafer-scale chips and sells speed: the same open model streams out tokens at rates that change the feel of real-time conversation and code completion.
A cloud API with free credits makes it easy to benchmark against conventional GPUs. The catalogue is limited to models they host, capacity and pricing move with demand, and it is best treated as the low-latency layer for a subset of workloads.
What it does
- Wafer-scale inference with very high token throughput
- Cloud API with free credits to evaluate
- Supports mainstream open models and function calling
- Low latency for streaming and completion
Best forReal-time chat and voice backends, Code completion with tight latency budgets, Benchmarking inference speed
FAQ
How much does Cerebras cost?
Usage-based API pricing; free tier for evaluation.
Who is Cerebras for?
Typical uses: Real-time chat and voice backends; Code completion with tight latency budgets. Key capability: Wafer-scale inference with very high token throughput.
What are the downsides of Cerebras?
Things to watch: Limited model catalogue|Capacity and pricing vary with demand.